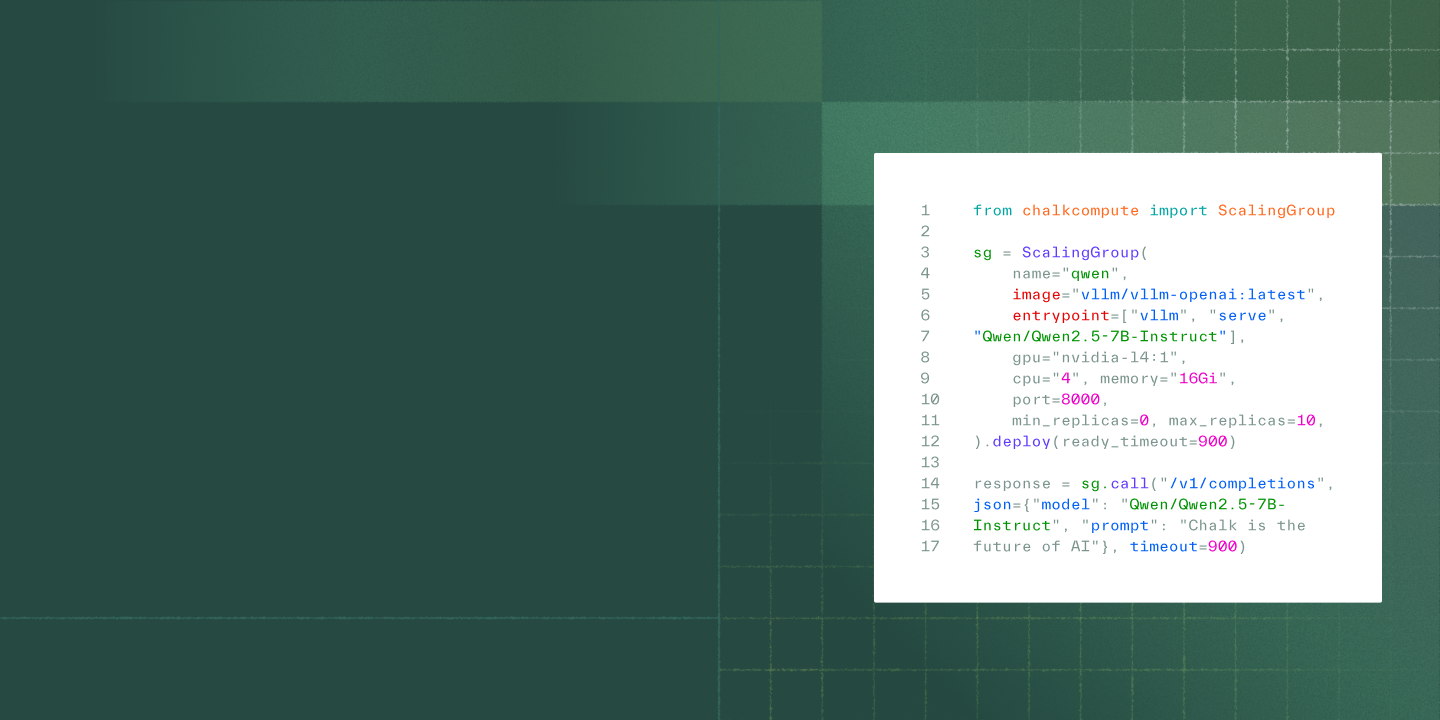
Model Serving
Serve models on autoscaling GPUs in your own cloud
Register a model from your training script and Chalk serves it on autoscaling GPUs inside your account, next to the data it needs. Call it from a feature pipeline, from a Chalk SQL query, or over its own endpoint.
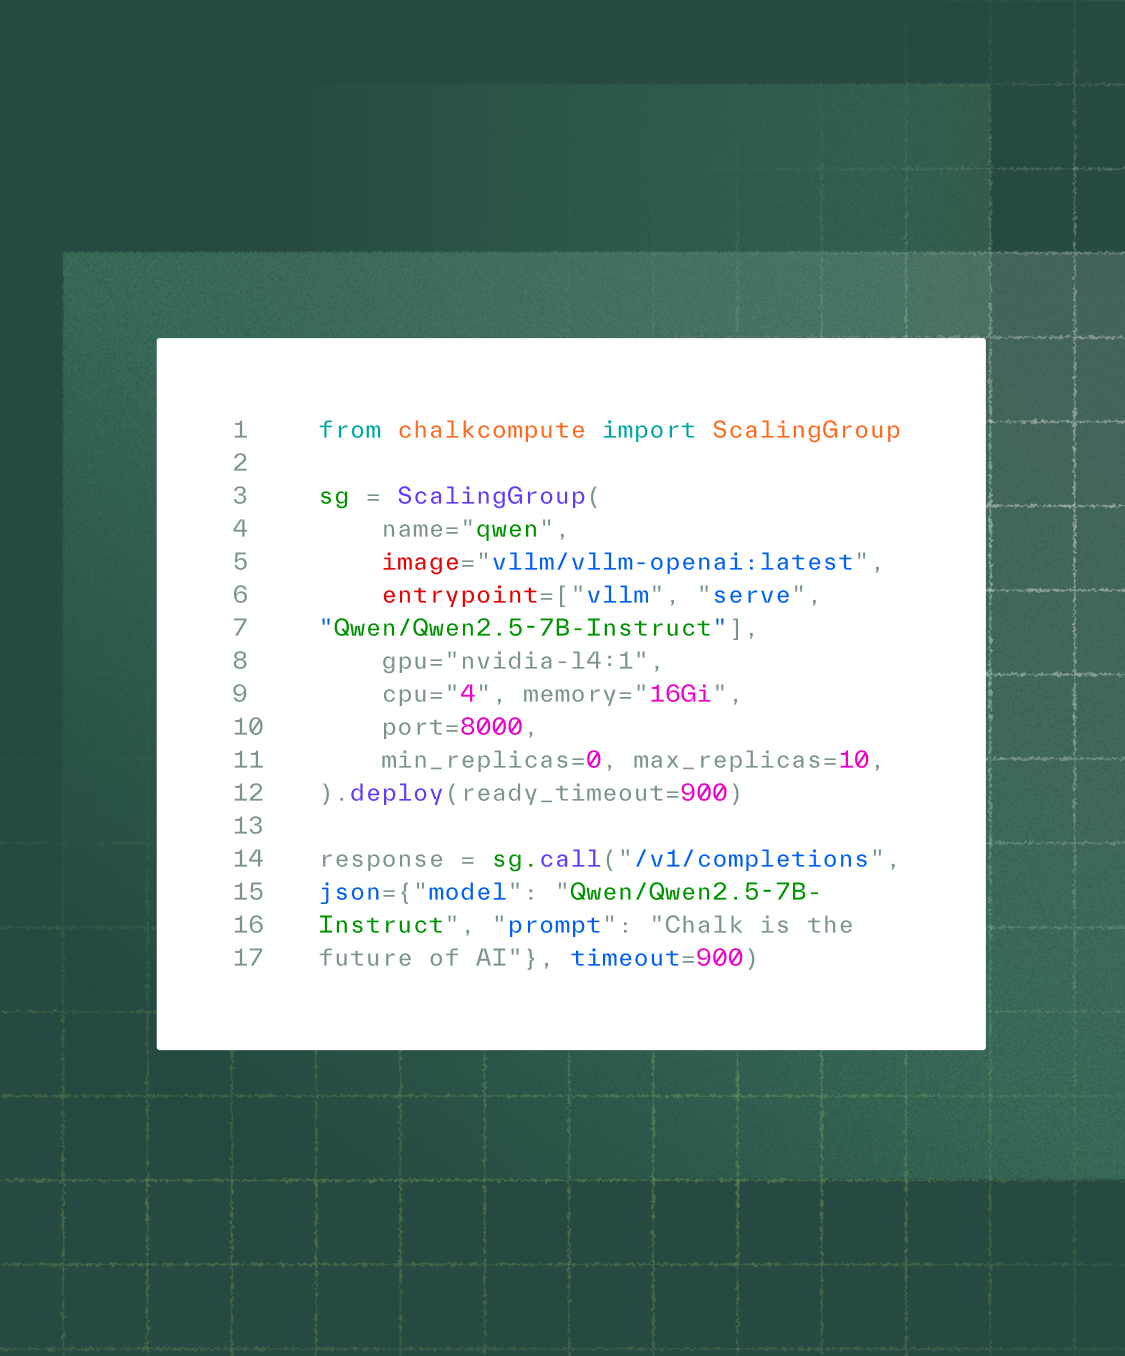




Explore Chalk Model Serving
Deploy models without MLOps
One call packages your trained model with its dependencies and versions it. No Dockerfile, no separate model registry, no deployment YAML.
Real-time and batch from one deployment
The same deployed model answers a live request and scores a backfill.
Weights and data stay in your account
The model runs in your cloud, next to the data it scores. Nothing leaves.
Scales with traffic
Set a target utilization with min and max replicas, and Chalk scales up and down with traffic.
Weights on a volume
Mount model weights from a persistent versioned volume. No container rebuild for retraining.
No schema to write
Chalk infers input and output types for scikit-learn, PyTorch, XGBoost and CatBoost models.

Verisoul’s team now writes less code while shipping more powerful models - freeing up engineering resources for higher-value initiatives.
Serve models next to your data
Your model doesn't have to round-trip to another vendor's platform: it runs in the same environment as the data it needs.
Calling Deployed Models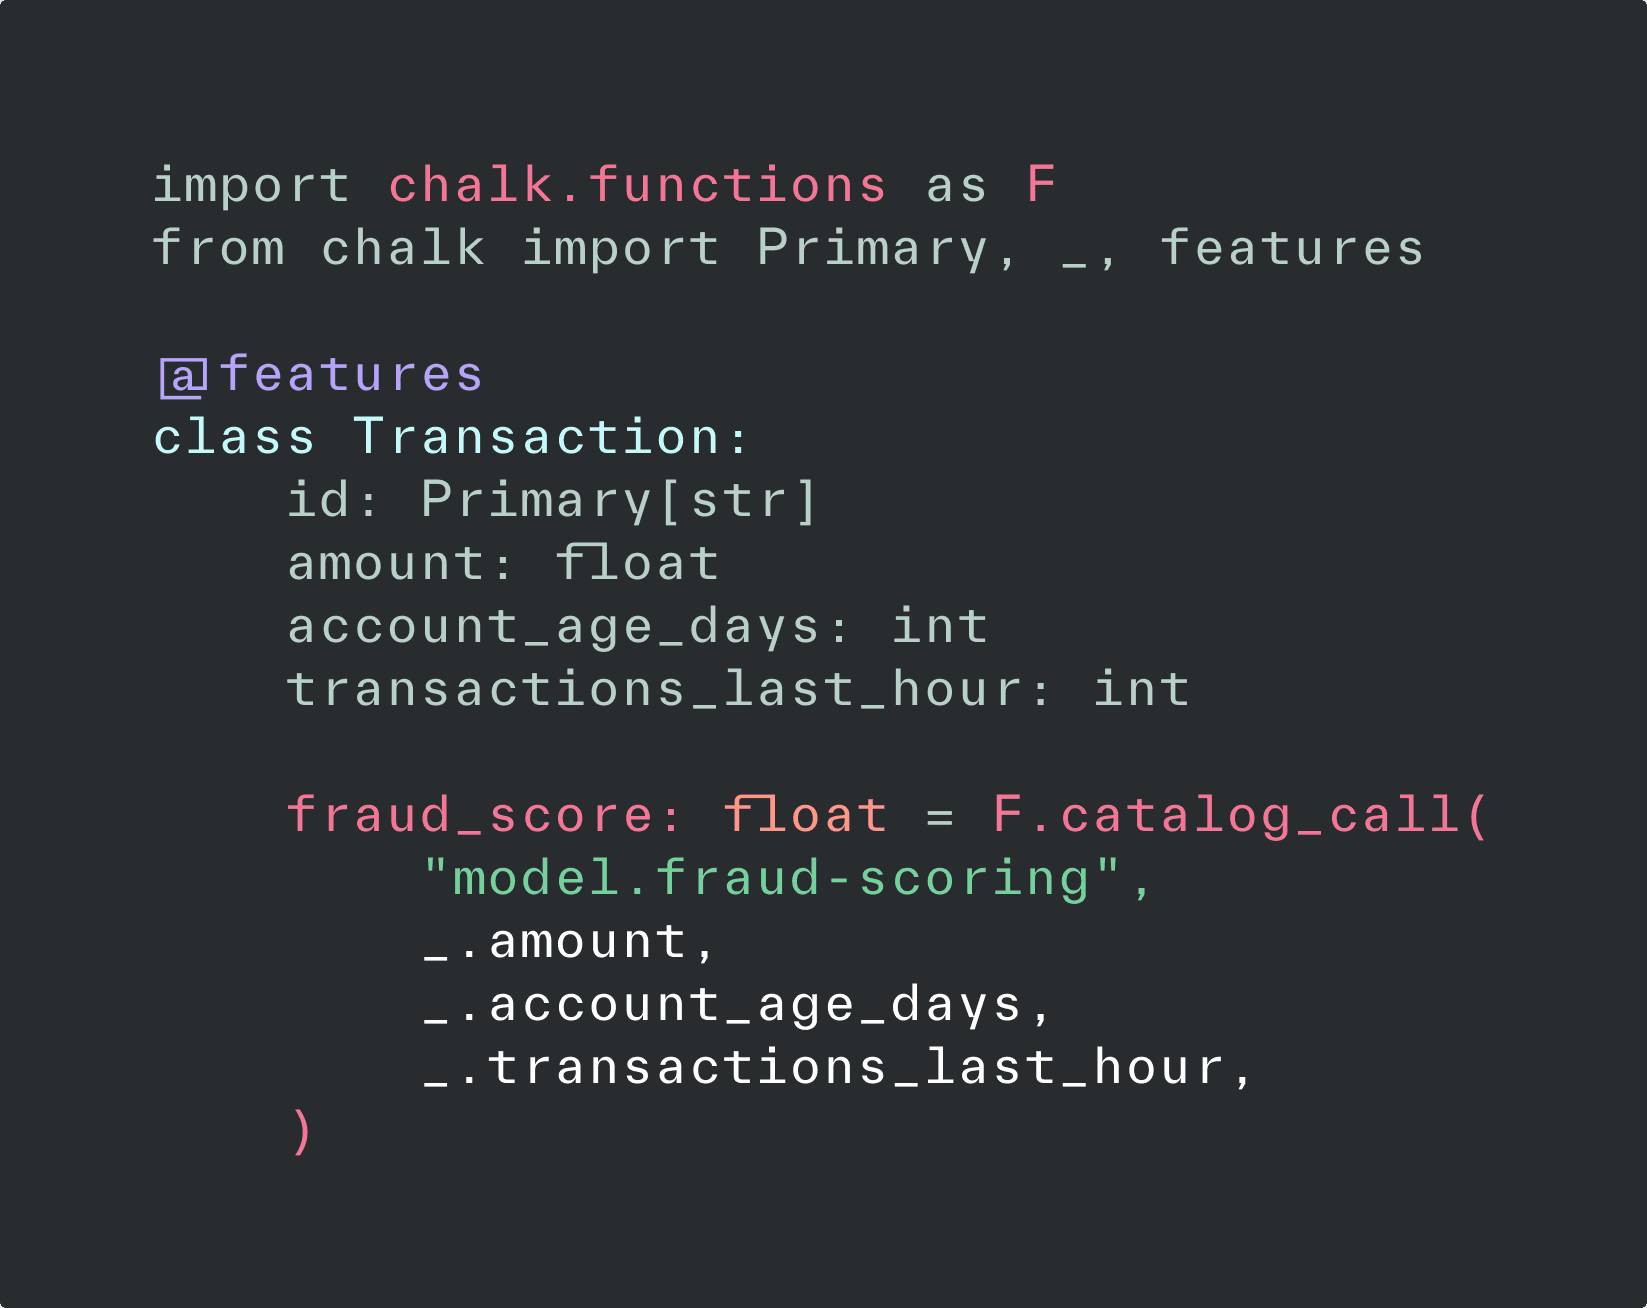
Keep up with Chalk
What we've been up to and where to find us next.
Most Innovative Companies
See why Fast Company named us on their list.
Register for the upcoming webinar
Learn how to give agents context for evals and production
Raising the Talent Bar
How Chalk filled 40+ roles in one quarter without lowering the bar
Introducing Chalk Notebooks
Read more about our latest product announcement
Ship the model without a new platform
Talk to an engineer about scaling model serving in your cloud.