Register your sources
Each database and warehouse you register becomes a catalog you can browse.
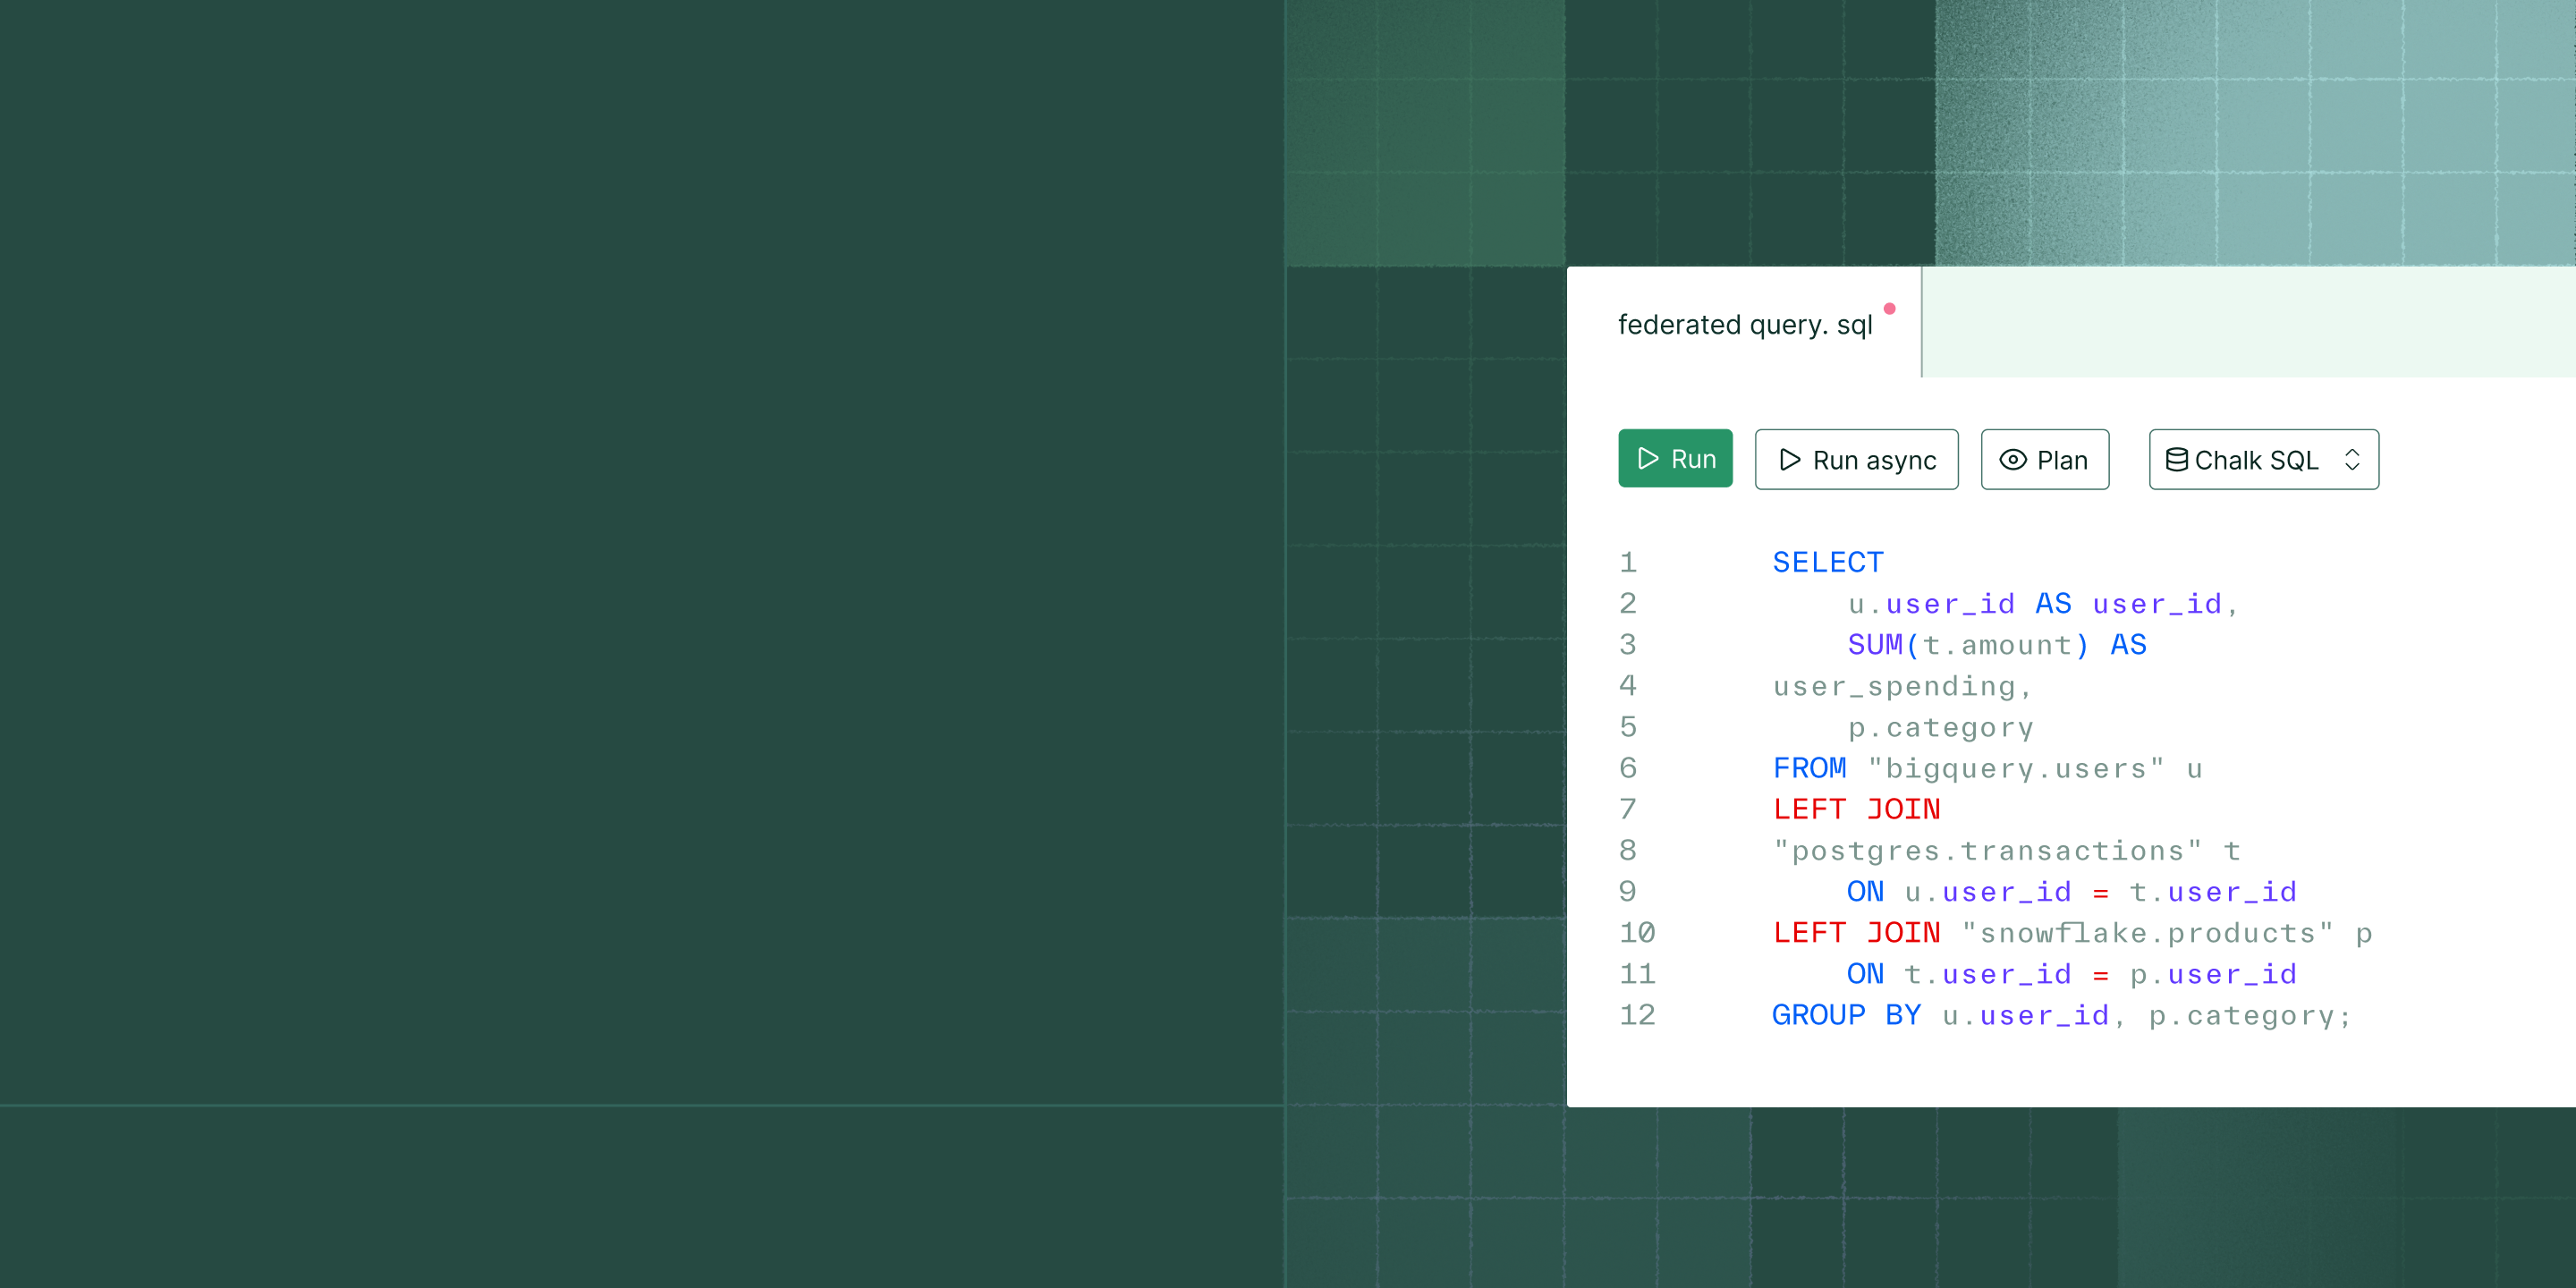
Chalk Catalog ComponentsOne query joins Postgres, Snowflake, BigQuery and the rest of your sources including APIs and streams. The result feeds a feature, a training set or an agent's tool call. Chalk queries each source in place, at inference time or in bulk.
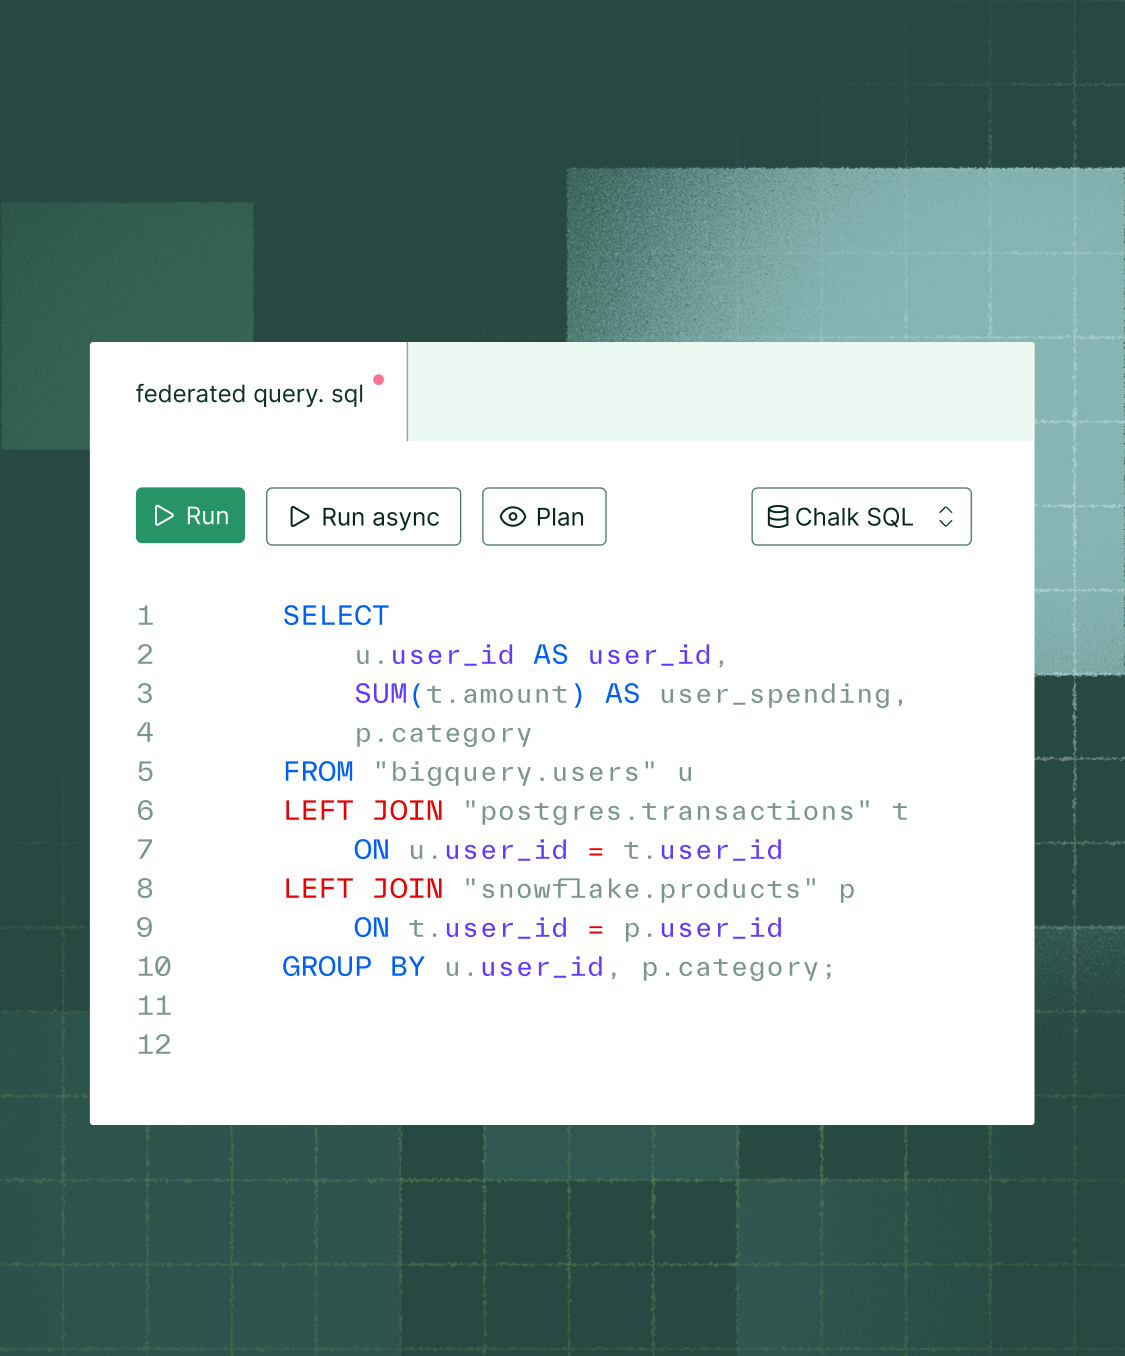




Join Postgres with BigQuery in a single query.
Postgres, DynamoDB, MySQL, Iceberg, ClickHouse, BigQuery, Turbopuffer, Redshift, Snowflake, Databricks and more. Anything else with Python.
Attached catalogs are read-only and scoped to the session. No connection opens until you run a query against it.
Write Python that pulls from a REST API, an S3 bucket or a SaaS app, and access its output as a table in the same query as your sources.
Pass Chalk SQL to online and offline runs without input lists or intermediate exports.
Review every registered source, schema and view with SQL Explorer.


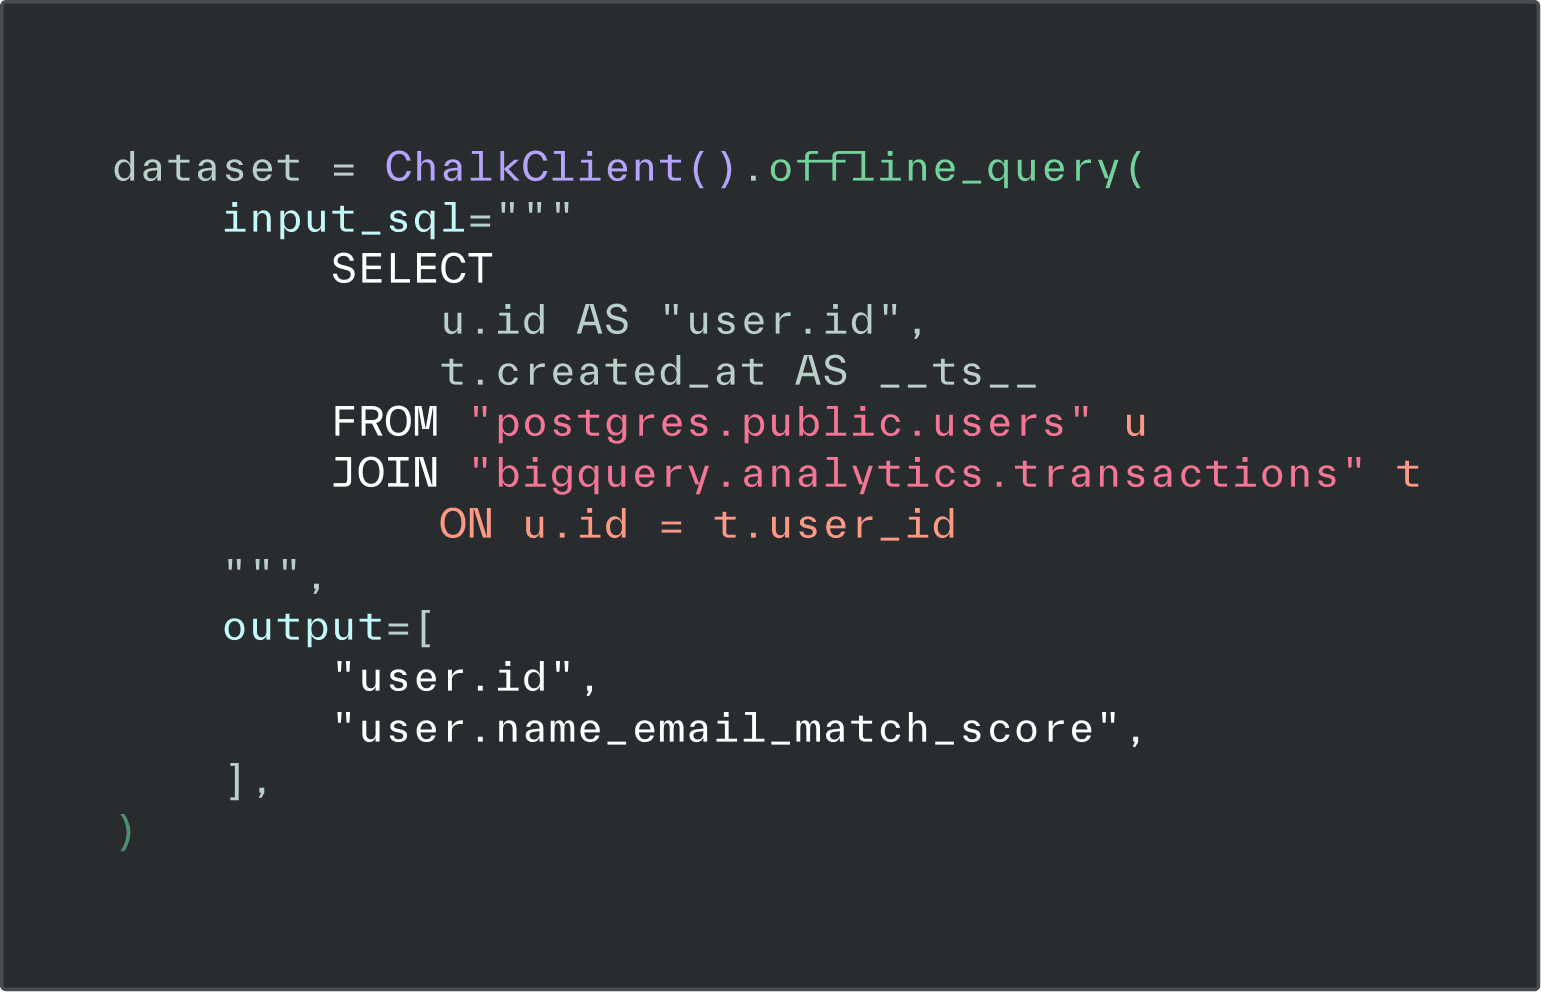
Each database and warehouse you register becomes a catalog you can browse.
Chalk Catalog ComponentsThe datasource name is the catalog name, so the join reads normally.
What is ChalkSQLPass Chalk SQL directly to a feature query or training run. Chalk dynamically resolves it without intermediate exports.
SQL as InputMost data platforms require a migration to work. Chalk registers every source where it is and queries it in place at inference time.
WHAT IS CHALKSQL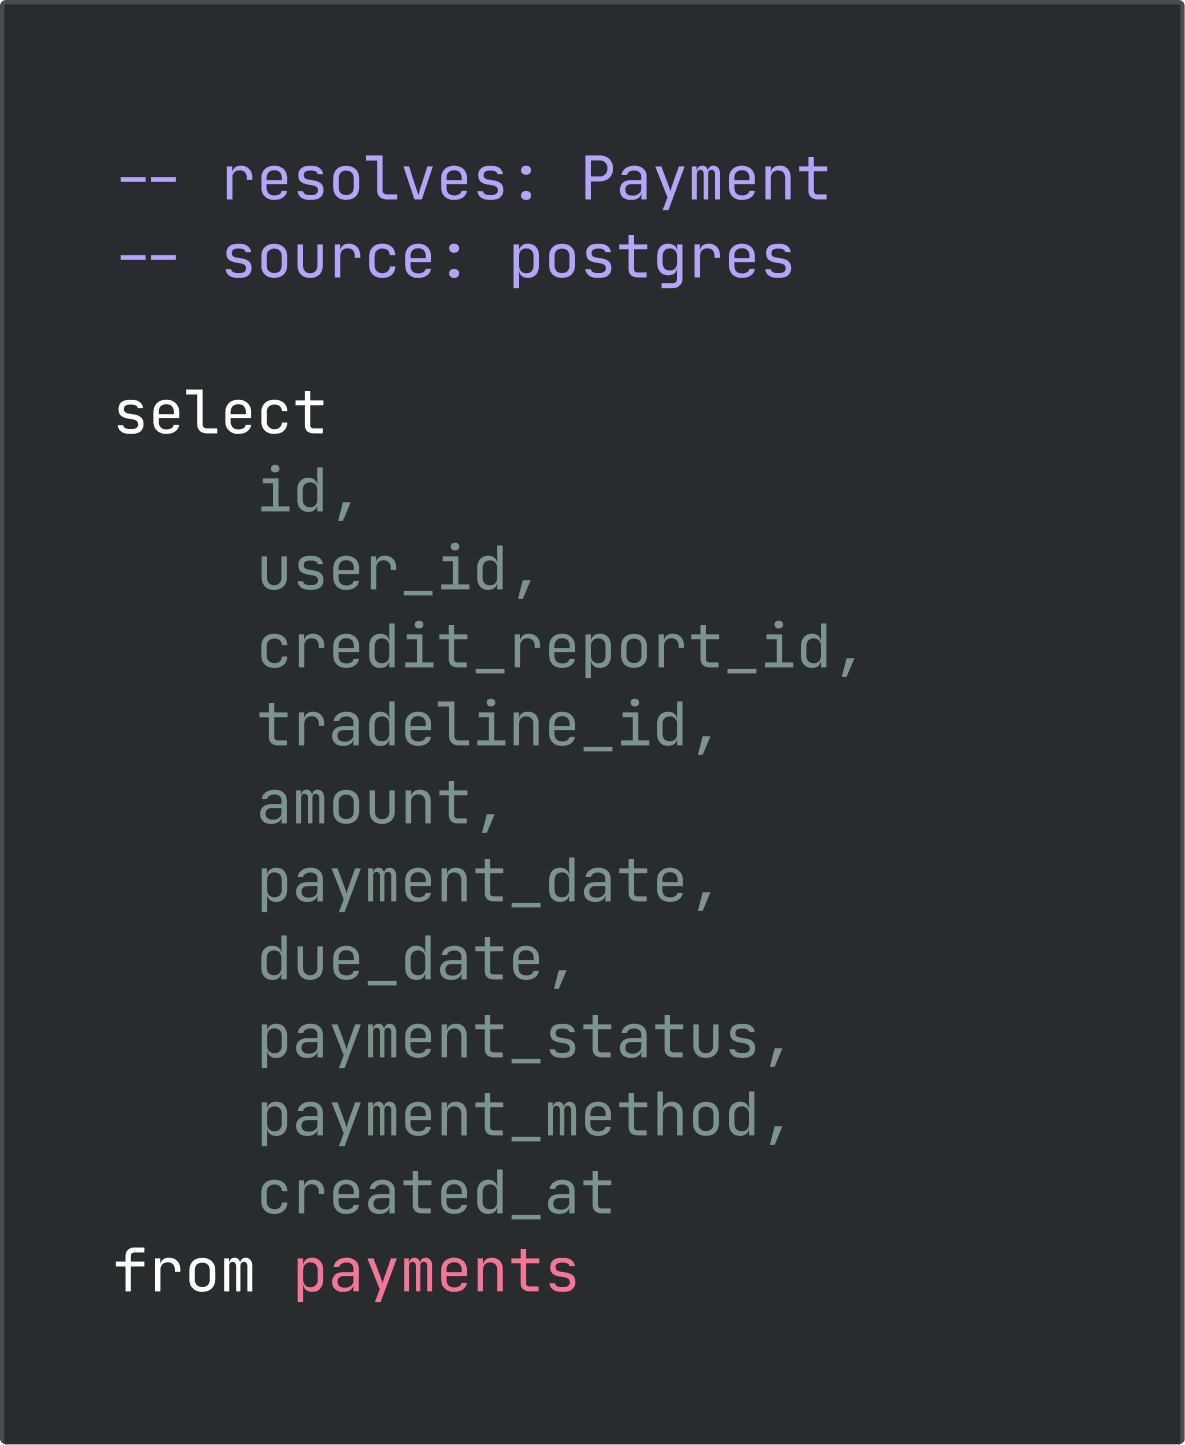
What we've been up to and where to find us next.
See why Fast Company named us on their list.
Learn how to give agents context for evals and production
How Chalk filled 40+ roles in one quarter without lowering the bar
Read more about our latest product announcement
Talk to an engineer about consolidating your data reads for models and agents.